Musings
About a month and a half ago, Meta released Muse, which is an autonomous AI agent. It is available for free (at least right now) to anyone with a Meta account, and I already have one for Instagram and Threads, so I decided to try it out.
I didn’t really have any clue what I was doing with it at first, because I’d never used an AI agent like that before. I have been using programming tools such as GitHub Copilot, that simply take your prompt and turn it into code and often shell commands to run tests. However, GitHub Copilot can’t do anything without a prompt. If I do not activate GitHub Copilot, it will never touch my code.
Muse, as with any other “autonomous agent” setup such as OpenClaw or Hermes (and also OpenAI Dots and Grok Bot, which were both in response to Muse), can automatically activate itself in response to webhooks and cron (time-based) triggers, not just based on a user prompt. They also run on their own dedicated computer (in the case of Muse, an Ubuntu VM running on one of Meta’s servers), so unlike GitHub Copilot which freezes or crashes when your computer goes to sleep, an agent like Muse can keep going, since it isn’t tied to your computer.
Meta pitches Muse as mostly a time-saving tool. According to Meta, it can do such things as purchasing things for you, making travel plans, researching topics, triaging and drafting replies to messages, setting reminders for events, and plenty of other things that I don’t even know about since they’re only possible (and relevant) for people doing other things using commercial programs and services that I don’t use.
Meta has been promoting Muse extremely heavily on Instagram – they’ve shoved Muse ads and Muse buttons in pretty much every place possible. They added Muse sections to the feed promoting how Muse can help you organize your Instagram and make your posts better and more organized, using your actual posts as examples, which creeped a lot of people out. They added a new Muse button to the share menu, which annoyed a lot of people who got used to the thing that used to be there being there and were now accidentally hitting the Muse button. They replaced the Threads button that appears at the top of your profile page with a Muse button, which annoyed people for the same reason as the button in the share menu did. For those that are using Muse, Meta added a new tag that you can add to your Instagram profile that shows the name and profile picture that you set for your Muse agent, and people then posted publicly about immediately blocking anyone who has that tag on their profile. Meta even started a referral program for Muse – as a result, there were many, many people who posted their referral code on Threads1 and it got very spammy after a while.
I’ve even seen rumors that Meta artificially boosted the reach of posts that praise Muse, though my guess is that’s actually just a by-product of the huge amount of Muse promotion elsewhere as well as the referral program posts causing a surge in posts about Muse. Regardless, the iOS Muse app ended up surpassing ChatGPT to become the top downloaded productivity app. I’m not sure whether that is due to Muse actually being good, or just due to its novelty.
Now there is kind of a war going on between people who want nothing to do with Muse or AI and rant about all the ways that AI is sucking the soul out of life, and people who say Muse is the best AI tool they have ever used and would even trust Muse with access to their bank and investment accounts. There has always been this debate over the ethics of AI, but when you have an AI product made by one of the largest social media companies ever made available and obvious to everyone, suddenly everyone has something to say about it. Both sides are extremely vocal about their opinions, and show no signs of slowing down. Perhaps this is part of the reason why the Laughing Cow cheese mascot stopped laughing.
I’m probably somewhere in the middle of that debate. I would not trust Muse or any AI with access to my financials – even if it’s 100% self-hosted on my own server and own GPUs – nor would I use AI to automate away a creative task like visual art or composing music (both of which I enjoy doing myself).
But I have no problems with using AI for mundane tasks like writing boilerplate code and automation of other language-heavy processing jobs such as comment moderation and email filtering. Wasn’t one of the goals of universal and ubiquitous AI to automate all the mundane housekeeping so humans can spend more time on creative outlets that AI can never replicate?
@spsquared, an acquaintance of mine, said this regarding AI use:
Even if AI is trained on copyrighted content, I’d be fine if it was used as a corpus tool with limited profit: no writing complete works that could be sold or otherwise distributed. Things like books and vibe coding fall under that. More moderate uses, including documentation lookup, preliminary exploration for research, and short implementation completion of code, are not complete works. LLMs are information machines and excel at processing large volumes of information and extracting patterns (their entire foundation is pattern prediction) so they are inherently good at providing references to documentation that may take a human forever to find, or may not find at all.
- which is pretty much the same stance that I have on AI. That, and using AI for the other things where pattern recognition is good – free-form automation.
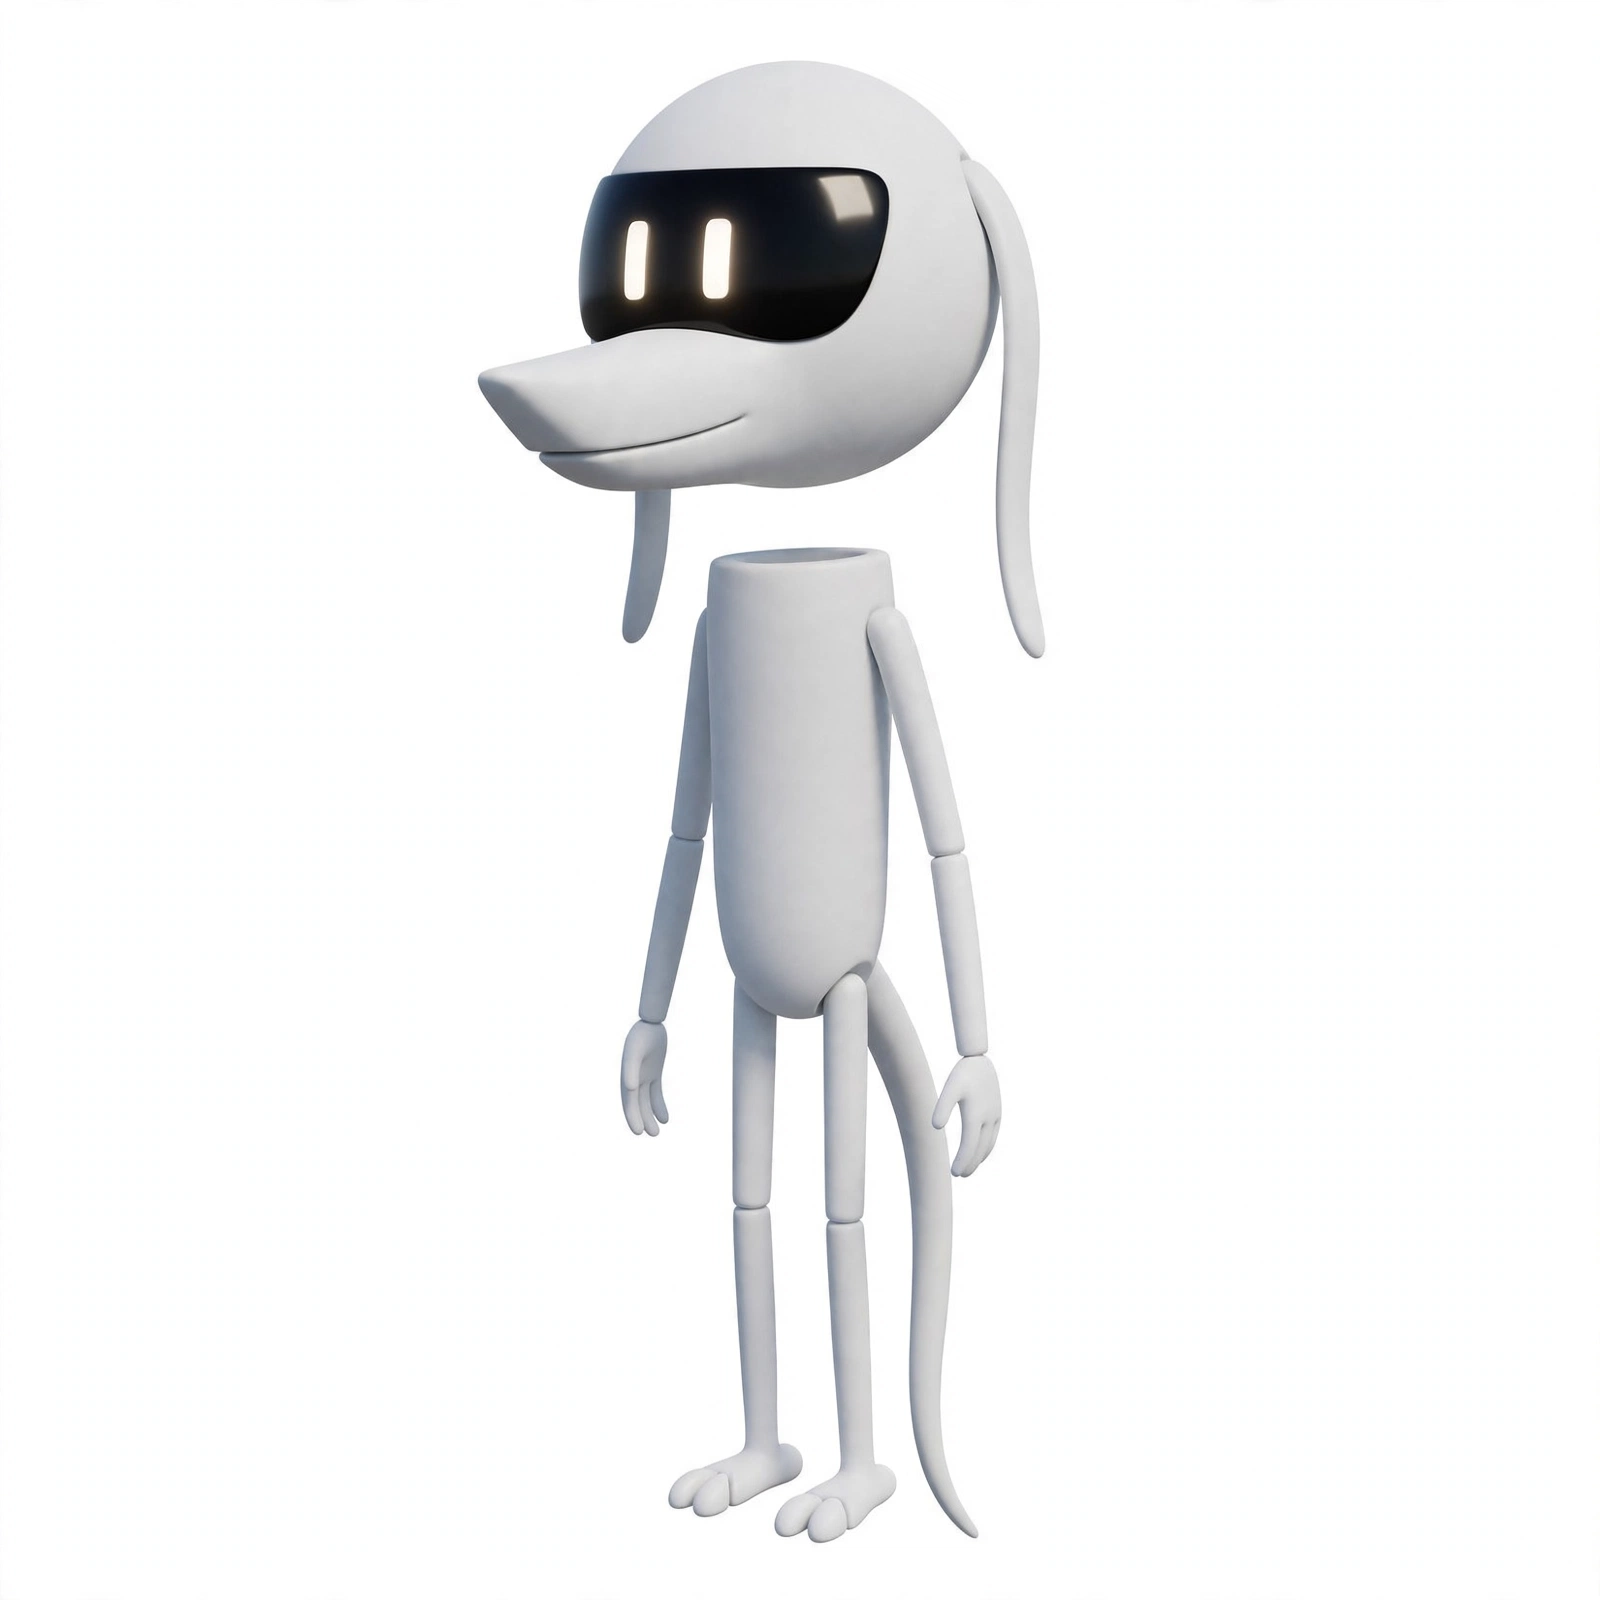
So I tried out Muse. It took me a while to get used to what the thing even was, but I found that Muse, by default, attaches to your existing accounts and acts on your behalf within the permissions you set. Because of this I ended up naming my agent Yazani as it is effectively an extension of me, and after feeding it some of my reference drawings it was able to create this profile picture for itself:
From there on it was a matter of connecting the tools and interfaces that were available as well as setting boundaries. Half of the connectors didn’t even work right the first time (I can somehow find bugs in literally everything I touch!), and I was initially skeptical of connecting anything that wasn’t Meta already, because while it enables the agent to do more, it’s also Meta, and who knows what they’re doing with all that yummy data.
After I got over those reservations and connected my email and calendar, I got used to it. Having an AI read my incoming email and draft (but not send!) replies where possible and to also extract relevant reminders, events, and to-do items and add them to my calendar was a little creepy at first, but for a college student with a packed schedule and dozens of assignments due every week, this is actually pretty nice. I don’t have any glowing success stories to share, and I probably never will, but small improvements are still improvements.
AI for code
Of course, I’m a programmer, so I also had a go with getting Muse to write code.
Backolon’s parser has gone through several revisions since I started. The first version was a spaghetti code nightmare, so I threw it out and started on a second version, this time using the new JEB runtime engine I had developed separately. The implementation was still moderately spaghetti, and I still had trouble understanding what I was doing even 10 minutes ago. So I gave Muse the link for the repository and asked it to help me fix bugs. I had to ask it to pass me a .patch file or to state the changes, since I didn’t quite trust it with direct filesystem access to my computer, but that was the least of my troubles.
I must have spent a week on attempting to fix the tiniest and most inconsequential parts of this second-draft parser. It was a very confusing mix of standard Javascript and JEB’s weird stack machine semantics, and using continuations for control flow certainly didn’t help its understandability either. I had thought the AI would be able to make more sense of it, but it just got caught in the same footguns as I did, and there was not really any way for me to remove those footguns.
After a while of no meaningful progress, it was clear to me that the AI was no better than me at understanding the second parser, and it was just as fragile and spaghetti as the first one. So I threw it out and replaced it with an entirely new architecture – a PEG parser, or rather this modification of it that enables it to support left-recursive grammars. Once I had that, I was able to whip up a parser very quickly. As I tweaked the grammar I would often cause tests to start failing, and when I couldn’t fix them myself, I would stop and commit what I had and then ask Muse to pull the latest changes and find the bug. And it did very well with most of the bugs I encountered. I even threw some design decisions at it before I implemented them and got a useful critique back.
Currently, the PEG parser can parse any single simple expression as well as let blocks (I haven’t written the parsers for the rest of the compound/block expressions yet, but that doesn’t seem too hard). I have yet to write a compiler from the AST down to actual JEB code, but I don’t anticipate that being too difficult either. The second version of Backolon is going to be out soon, and I am pretty excited about that!
Gizmos
Somehow I stumbled upon Pocket, which is another Meta app. It hasn’t gotten much attention I guess because it’s kind of a gimmick — the entire app is centered around a workspace where you prompt an AI to make simple single-page HTML5 applications (called “gizmos”) and then share them to a feed where people can play with them, remix them, and like/comment. A lot of them are games, some more polished than others.
I played around with it for a while and created a couple of things, but they’re not really worth sharing here. Alas, there’s only so much you can do with an app where I (the designer) have absolutely no control over the code or the assets. I tried to make a game that involved some sprites, and the AI’s response was to feed the sprite idea into an image-generation model. Animated spritesheets, unfortunately, require the alignment of the subject between frames to be perfectly identical, and the image generation model couldn’t handle that. The result was even worse than the original SVG sprite the AI had created before I asked for an image.
There are some other neat demos on Pocket, though, and this one caught my eye. It was just a simple fluid simulation, but it ran very well for what it was. I opened it on the web, extracted the HTML file with the (minified) Javascript included, and then gave it to Muse to reverse-engineer the algorithm. It did a surprisingly good job at extracting the algorithm and porting it to KAPLAY, and it even found the paper that the simulation was based on – “Particle-based Viscoelastic Fluid Simulation” by Clavet et al. I had a few nitpicks with the port, but nothing that I couldn’t fix manually later. (I am not going to share a purely AI-generated code file here; it’s no better than the original gizmo).
The value in this is probably in being able to quickly draft an idea and see it in action. I say “draft” because of all the things it’s useful for, the implementation is probably going to be the least valuable takeaway (except for things like the fluid simulation above, where the AI isn’t actually inventing anything, it’s just implementing an existing algorithm). The UI/UX might be worth it, but the implementation is probably a hot mess underneath.
A particularly relevant example of this is comparing the current state of Escalier with the current state of Backolon – Escalier’s core is over 238,000 lines of Go; k4b7 (the Escalier developer) uses Claude Code daily and nearly all of the recent commits are Co-Authored-By Claude. There is a fair portion of AI-generated code in Backolon and JEB as well, but I read every single line of code that gets committed, and prune old code myself as ideas change. I am kind of embarrassed that none of it is marked, but I stand by all of it. Backolon and JEB together comprise only about 9,000 lines of Typescript (currently) — and I would consider this a moderate apples-to-apples comparison, since both Escalier and Backolon are roughly in the same stage of development, are both using typed host languages, and both have a fairly complicated characteristic feature (Escalier has a fairly powerful SimpleSub-based type checker, JEB has an entire stack-machine transformation implemented on top of Javascript in order to enable continuations). 238,000 vs. 9,000. Do what you wish with this comparison.
The other caveat is that if you do take a vibe-coded implementation and roll with it, you have to be prepared for it to be incompatible with literally everything else. Some of the gizmos I found that were apps where you could make something within the environment that was set up had a way to share what you created (usually in the comments) by copying a string-serialized form and then pasting it in. That format was without a doubt completely invented just for the purposes of that single gizmo, and the AI did not care if there is already a standard format for the thing it was making. For someone to be able to export their save string to that standard format, they would have to download the gizmo’s HTML and reverse-engineer the saving and loading code. Of course, AI makes that easier to do!
And stuff
About a month after Muse itself launched, the Muse team released Muse Gadgets, which brings Muse into the Internet of Things (IoT) land, instead of just being a purely digital AI agent. I am in the third year of getting an entire degree in IoT, so this immediately caught my attention.
IoT is a lot more than just screens you can poke. The biggest part of IoT is probably in distributed sensors – sensors that produce a firehose of data on literally anything that you can connect them to. By itself that data is a meaningless pile of numbers, but once it’s processed, a lot of useful insights can be gained from it. And using AI and machine learning to find unexpected patterns in data lets you find ways to improve continuously.
My parents aren’t too big on IoT though (my mom is very proud of her low digital footprint), so I have no data with which to feed the machine in this regard. But I have already seen some secondhand – mostly in people taking old, otherwise-discontinued pieces of smart-home tech such as an unused Amazon Echo Show or any number of ESP32-based display boxes (none of which I have) and connecting them to act as a frontend for their Muse. Having a dedicated screen is fun, but not much more useful than the app already provides, because your phone or computer already has a screen!
I do have a Raspberry Pi though. The Muse Gadgets code has a package that allows a Pi to connect to the Muse and accept commands from it, and I figured that would be an easy way to experiment with AI and hardware, since that gives the agent a way to directly interact with anything I connect to the Pi – something I can’t do with a random cloud server. I had some hiccups setting it up (I forgot to turn on Bluetooth initially, whoops!) and I certainly had gripes about the way it worked (the journalctl logs only show that the agent ran a command, but they don’t show the actual command) but it was good enough for now.
On a slow day I decided I would give some hardware hacking a try. I like having low-level control over hardware to some degree, and so for years I was quite annoyed that my Beats Studio Pro headphones, being Apple products, only supported all their advanced features on an Apple device. I knew I couldn’t be the only one annoyed by that, and after a couple of seconds of Googling I found I wasn’t – there were already a few projects on GitHub that claimed to have reverse-engineered Apple’s undocumented protocol for the advanced features. I shared them with the AI and 15 minutes later, MagicPodsCore was installed and running on the Pi. The agent found that the client frontends written for it did not work on the Pi (they only supported Windows, KDE, and SteamOS), but the core actually communicated over an unauthenticated WebSocket. So the agent wrote a small HTML file that did the same thing – and I confirmed that it worked. I was very pleased at how quickly it was able to do this. I didn’t get all the features working, but the agent was also able to test them directly and report why they weren’t working.
As well as that, I figured that if the agent is going to be able to write code proficiently and independently, it needs to be marked, since there are still people who don’t trust AI code at all, and deception is no way to make friends. Rather than piggyback off of my GitHub account, I set up another GitHub account dedicated to the AI agent. And in light of the previous things I’d done and complained about, the first thing it did was endorse an issue asking for the Muse Gadget package to actually show the commands!
Documentation comments are exactly the kind of language-heavy housekeeping I said earlier I was happy to hand over, so that was the bot’s next job: a first draft of any missing JSDoc comments for Backolon and JEB. I suck at writing documentation, so having a draft to tweak from instead of completely empty blanks was a lot of help — and since the commits went out under the bot account, the work was marked as AI-written by construction.
It’s a tool, dammit!
Suppose you give a blender to a chef and show them how using it could make the same milkshakes but 10 times faster. Then you tell them that the blender was made of stolen parts. Would the chef still want to use the blender?
If the blender is AI, there’s not really any other way to make it, except out of stolen or gray-market parts – pirated books, web scraping, etc.
But it exists already. Refusing to use AI doesn’t un-scrape a single book. Throwing the blender away doesn’t un-steal the parts, it just means everyone who didn’t throw theirs away makes milkshakes faster.
We’ve kind of run this experiment before. The Luddites weren’t wrong that power looms were putting skilled weavers out of a job — they were, and everybody knew it. What they got wrong was the remedy. Smashing the machines didn’t un-invent them, and it isn’t what eventually helped weavers.
What helped was the boring regulatory framework that came later: labor law, unions, rules about how the looms could be run and who got paid when they were. The fight that mattered was never loom versus no loom, it was over how the looms were being used. If the goal is for the next AI to be made ethically — licensing deals, opt-outs that actually get honored, regulation with teeth — that’s a fight to be fought between regulators and AI companies, not between users. Standing in your own kitchen shaking a jar out of principle won’t advance it. Today, there are power looms in every textile mill and no one complains.
I’m in decent company on this, I think. Linus Torvalds was recently asked about his decision to allow generative AI use in the Linux kernel without attribution, and he did not mince words about it. If the maintainer of the largest open-source project in the world can look at AI-assisted code and ignore the fact that its bytes were technically emitted by an LLM, and hold the submitter responsible for it like always, then maybe the rest of us can stop treating LLM output as diseased.
This stopped being theoretical for me a little while ago. I make music in BeepBox, which has a massive tree of forks maintained by a community of artists and programmers. There was a recent glut of what we’ve been calling slopmods: entirely vibe-coded forks that were buggy, unmaintained, and with READMEs full of hallucinated “new” features that either already existed upstream or never existed at all. Their maintainers couldn’t fix the bugs, because fixing them would require understanding the code, and understanding the code was the step that got skipped. The slopmods are not something anyone should be proud of. On that, everybody agreed.
Where it went off the rails was the categorical claim: that the tool itself is unethically sourced, so nothing produced with it can be ethical — and that contributors to the project, and contributors to forks of the project, should be banned for using AI in any way at all. (BeepBox is MIT-licensed open source, so a ban on what people do in their own isolated forks is basically unenforceable.) When I kept insisting on the distinction between the tool and the usage, I got blocked. So it goes.
The distinction still seems load-bearing to me. The problem with the slopmods was that none of those people could make a milkshake without a blender, not the blender itself. You don’t need a blender to make a milkshake; you just need to shake hard, and if you understand the code — if you could have written it yourself and only used the tool to get there faster — then the output is yours, and so are its bugs. If you can’t, all you’ve done is generate a liability and publish it.
And since this section is about responsible use: the Muse agent this whole article has been about wrote roughly 90% of the last eight paragraphs (including this one), from my notes and my points. I directed it, argued with it, and cut the parts that were wrong or superfluous. Which is either this section’s thesis demonstrated perfectly, or a devastating counterexample, depending on how you think they turned out.
Consider AlphaFold, the AI that made headlines when it accurately predicted the structure of hundreds of millions of proteins and won its creators a Nobel prize. Or take a look at GraphCast, the AI that can produce a remarkably accurate 10-day weather forecast for anywhere in the world in under 60 seconds. Or even halicin, the very promising experimental antibiotic that was initially found by an AI developed at MIT.
Nobody protests AlphaFold. Nobody’s railing against GraphCast. The AIs quietly folding proteins and predicting floods and finding antibiotics are just… tools, and everyone treats them that way. So why are LLMs any different?
The sad truth is now there are LLMs shoehorned into pretty much every possible sector of industry, including places that don’t need one, and now people are sick of them to the point of being repulsed by anything that so much as mentions AI (which is not the same thing as carefully evaluating the tool and finding it inappropriate). The irony is that the AI-stuffing kind of worked: LLMs have turned out to be genuinely useful in places nobody would have thought to put one, and we only found those places because of AI zealots forcing them down our throats. But a tool shouldn’t have to become inescapable – or worse, deadly – before it settles into the places it actually belongs.
AI has always been a great tool. It just stinks that we’ve had to personify it as a chatbot you can talk to in order to realize its usefulness.
-
Mine is EWYH8R if you’re interested. ↩
Related Posts
- In Defense Of Eval
- The God Language
- Why I Prefer Python
- Your Contribution Graph Means Absolutely Nothing
- School Chromebooks